Matthew J. Westerby opens his article “Annotating Upstream: Digital Scholars, Art History, and the Interoperable Image” with the story of how downstream uses of the British Library’s IIIF images and manifests lost their own access when the Library was the subject of a cyberattack. This domino effect showed a “change in the relationship between institutions and users of online collections in which separate layers exist to serve images and also to present the digital surrogate of a real-world object like a book.”1 Similar complex layers of delivery and downstream/upstream usage have been on the minds of video game scholars for a long time. There is always a layering between the game’s software and the hardware or the display, as well as between the game as code and the physical object that carries that code, such as a cartridge. Especially with online-all-the-time consoles, a game can be pulled or updated or changed at any time without user consent or warning. These delivery layers are perhaps more apparent to the average gamer than the average user of an IIIF image art surrogate because they have demonstrably affected how games are released and experienced. It is now common (though not acceptable) practice for a game to release in a broken state with day-one patches to download. Patching post-launch was a near impossibility before internet-connected gaming, so the uneven quality of games at release has been felt by all video gamers.
This is not the only place where Westerby’s suggestions and insights for art history run parallel to emerging practice in game studies. Annotating video games is one way game studies is looking to share knowledge weither via annotating games themselves, annotating screen captures of video games, or through examining existing annotation practices like wikis and let’s plays that are a part of the larger life of “networked hyperlinked videogames”.2 For the practice part of this post, I used Panopto to experiment with annotating a brief screen capture of me playing The Blood of Dawnwalker.3
Panopto was the assigned tool for class but I didn’t find it particially useful for the annotations I would like to make where it would be helpful to have them show up on specific parts of the screen during viewing.
One of the reasons wikis are such a robust source of information for video games is that they are such complex artworks that one person could never annotate a full game by themselves. It also adds to the robustness of scholarship when sharing is part of the process, not just the outcome. The Zelda object-focused digital humanities project4 that I mentioned in my post about Collection Builder was one project that used this style of sharing. My portion was about multiplicity and repetition of objects in the Zelda series, focusing on small keys, but I was doing it alongside Sydney Bauer whose object was a single American painting, Hannah Iovanna who was examining the still life paintings of a single artist, and Addie Magyar who worked with me on the Zelda portion and also acted as coordinator (Magyar was actually who noticed that small keys are the only constant in all the games). Being able to do those separate case studies with the same methodology while in communication during the process made the projects much richer and more enjoyable. Our discussions and brainstorming sessions brought up the question that I swear one day I will write about: why is there always a wheel of cheese with one little slice out in every video game? I sometimes wish I had picked the history of the wheel of cheese with one little slice out as my art history thesis: a study of why it is the most filling and delightful of foods across time and medium.
Annotating interoperable images is a mode of scholarly communication that is fundamentally different from the traditional sharing of only finished writing in journals and academic press books but no less a creative or scholarly act.5 When there’s a wider variety of acceptable ways to communicate information, writing a book or a journal article becomes a choice, not an obligation. The quality of all scholarly communication increases as forms increase because the output mode is not just one default option regardless of the needs of the argument or the data. This also allows for more modes of scholarship that cannot be studied or communicated as well via paper alone, like GIS mapping projects from my previous post. I was unfamiliar with the idea of thick data or data pollution6 as terms when I wrote the mapping post, but they are great terms for the concept I was exploring at the end of that post: messy data that balances the line between being so messy it’s no longer a useful tool but isn’t so clean that it carries unquestioned authority with data pollution also covering the source of data like AI or how data is used.
Westerby’s choice to end the article with how you can’t control other people’s usage of your images or metadata if you share them, and how the fear of misuse should be a known risk but not a reason to abandon openness was nuanced and powerful.7 There will always be people who take good things and warp them. Making decisions based around absolute prevention of misuse is an impossibility and an unnecessary burden. It is better to work from being risk-aware, with practices like the usage tags that Westerby suggests.8 It reminded me specifically of the Wretched & Alone SRD,9 a system written by Matt Sanders for making solo journaling games in the style of Chris Bisette’s game The Wretched.10 The Limitations section of the SRD includes “Finally, nazis, homophobes, transphobes, and other bigots are expressly forbidden from making new content using the Wretched and Alone system. If you have to ask whether this includes you, it does.”11 Are parasites going to ignore the usage terms? Likely. Still, by making clear the usage and specifically taking a stance on who is forbidden to use the material, bigots cannot hide behind not knowing or accidental infringement. It makes the deliberate nature of the theft apparent.
Matthew J. Westerby, “Annotating Upstream: Digital Scholars, Art History, and the Interoperable Image,”Open Library of Humanities 10, no. 2 (2024), https://doi.org/10.16995/olh.17217.↩︎
Austin Anderson, “Dark Souls as Networked Hyperlinked Videogame,”Electronic Book Review, ahead of print, September 28, 2025, https://doi.org/10.64773/1f7a-df6c.↩︎
“The Blood of Dawnwalker – A Dark Fantasy Narrative Sandbox RPG,” The Blood of Dawnwalker – A Dark Fantasy Narrative Sandbox RPG, accessed October 5, 2026, https://dawnwalkergame.com/us/en/home.↩︎
Working on the Artist Book Critical Index (ABCI), I’ve already gotten to work with data I really enjoy: linked data, the semantic web, distributed knowledge graphs. I enjoy ontology and vocabulary creation and being part of building semantic frameworks that other organizations can then pick up and use.
Angela Dressen’s “Cultural Heritage Data for Research – An Introduction” covers semantic web work in the art history space with clear appreciation and understanding, but in the Linked Art section, it also presents the idea that with proper tools, you then don’t need data scientists in the museum space.1 The idea that if the structure’s in place and it’s easy enough to use, museums don’t need data professionals in permanent positions is part of why digital humanities projects fall short or become obsolete. When data projects are approached as short-term, quick-burst projects, they die out quickly. Not because the data isn’t good anymore or the tools are bad, but because there is no one cranking the engine to improve the data and move the project forward. If there’s one thing I’ve learned working on the ABCI, it’s that there has to be human energy for all aspects of the project, including the data handling and project maintenance.
The ABCI started as a Zotero library made by the Sloane Art Library’s now-retired manager, Josh Hockensmith, who is a book artist. He was making an index of reference works connected to artists’ books: where they were cited and on what page an image could be found. Graduate students were then assigned to the project and started expanding beyond UNC’s own collection by adding WorldCat links. It is a really unique, robust data set that could only come from human beings.
One of the key points Broman and Woo make in “Data Organization in Spreadsheets” is that the raw data should live in a different place than where it is analyzed and manipulated.2 This was one of the untidiest aspects of the original Zotero ABCI library. The workflow for photographing artist books was living in the same Zotero, and it was difficult to untangle verified entries from unverified ones, even when they were marked with workflow tags.
We also had to deal with missing data, the equivalent of what Broman and Woo talk about with leaving cells empty.3 The early ABCI entries had full metadata. But as the point became simply tracking citations between books and linking to the catalog entry at UNC or WorldCat.org, entries started having just author and title, with no standardization in capitalization, author name order, or which creators should be listed. And because the citation information had to live in Zotero’s notes field, which is a free-for-all of text, we had to figure out some constraints, along with using Claude Code, to pull the citation data out and attach it to the items it belonged to.
One of my favorite parts of the process has been creating ontologies and vocabularies. It’s modeling how the data should look in triple format, in our case Turtle, with an example, because often when you start doing an example is when you start saying, “Oh no, that data would be great to have, but we don’t have that,” or, “What do we call a construction method?” Luckily, I was able to piggyback off the work of the Book Arts Research Database4 and Opening Artists’ Books5 for reference.
Sometimes a tool becomes unexpectedly good at another job, in this case, metadata checking. One unexpected side effect of the ABCI has been pointing out where our catalog metadata was misentered or left out. More than once, the Sloane Art Librarian, Alice Whiteside, has asked me to use the tool to pull books with a particular construction method, only to find that a book is missing or mislabeled. If you are working with incorrect data to start with, you’re going to end up with incorrect data.
As for data I would like to work with in the near future, I’ve been fascinated lately by maps of crafters and craft spaces. Especially having read more of Brendan Keogh’s recent work about viewing video game developers as craftspeople, I’d like to make a network map of video game creators and the companies or specific games they’ve connected to. Art history already acknowledges that who an artist is taught by and where they have worked has a large influence on their oeuvre. This type of lineage study is not something I’ve encountered yet in game studies.
My first step for a network map of game artists/craftspeople would be to model one simple connection. I generally do not start in a spreadsheet but think with pen and paper about how the graph might flow and then start throwing it into Turtle triples. I would start with a relatively well-established indie or smaller-team game from a company where English is a primary language. From there, I would pick one creator in an art leadership role, like an art director or character designer, and work through their CV. Once I know what information I’m looking for, I’d break out the spreadsheet to gather everything about one person, translate it over, see how it works, and troubleshoot. Then I’d look to other sources of linked data I could link out to, like Wikidata. From there, whether or how to proceed to a larger scale would really depend on what the data revealed in the small model.
Dressen, A., (2025) “Cultural Heritage Data for Research – An Introduction”, Open Library of Humanities 11(1). doi: https://doi.org/10.16995/olh.18710↩︎
Broman, Karl W., and Kara H. Woo. 2018. “Data Organization in Spreadsheets.” The American Statistician 72 (1): 2–10. doi:10.1080/00031305.2017.1375989.↩︎
Broman, Karl W., and Kara H. Woo. 2018. “Data Organization in Spreadsheets.” The American Statistician 72 (1): 2–10. doi:10.1080/00031305.2017.1375989.↩︎
For a recent class assignment to make a Collection Builder exhibit, I created an exhibition of the first 10 boss fights from the mainline Legend of Zelda video games, specifically the final blow in each boss fight (https://beeyop.github.io/zelda-death-blow/). What weapon has to be used? Who’s involved in the fight? What part of the timeline, via the Hyrule Historia, does it come from? This was an expansion of a previous project where I looked at repeat objects in the Legend of Zelda series (https://sydbauer.wixsite.com/scaling-stories/zelda ).
I immediately ran into some issues. I couldn’t get the YouTube links to show properly if I wanted to start them at a specific time. I also struggled for a while trying to figure out why a thumbnail wasn’t showing, only to discover that it was an errant capitalization. Frustrations aside, Collection Builder did a really nice job of creating a professional-looking digital exhibition space. For that, I think it fulfills a valuable niche.
I only had one major criticism of the Collection Builder exhibits we examined in class: all the websites felt the same. By the second collection I looked at, that sameness made me gloss over and lose interest in the content. The visual layout was pretty much identical, even with different themes and some custom CSS. I think this is indicative of a larger issue. I believe many cultural institutions view tasks like metadata curation as mechanical, logical chores. In reality, it is a fusion of artistic skills and data skills. If the visuals and experience don’t feel curated to the data, then it is a cute toy, not scholarship or a tool. Some of the exhibits we examined did have a cohesive feel and told a clear story, but I don’t know that they did more than a well-annotated photo gallery.
I think Collection Builder is a gift for smaller museums, organizations, and student projects as a tool for displaying work when you’ve got one, maybe two people working and there isn’t room to expand. In some environments, finding someone with the education and experience in both curatorial work and digital tools would be very hard. Hiring online is an option, but then you run into control issues and management duties. In a single-person or very small team space, hiring out isn’t saving any time or workload the way I think Collection Builder does. I think the well-written and well-organized guide does most of the work of making it a better alternative for that use case. Anytime I wanted to know how to do something with my collection, the guide had an easy-to-understand, easy-to-find, simple process. I have some background in using GitHub and VS Code, but I heard from other people in the class that they also appreciated how well thought out the guide is.
What concerns me is that every time I see a tool like Collection Builder that makes what seems to be a mechanical task, like cataloging, display, or access, easier, I see organizations pushing people to do more with less instead of hiring someone to do these things or paying people appropriately for an increased scope of their job. Budget issues often become the scapegoat, but that is no excuse. Most individuals’ budgets are equally, if not more, stressed than those of any organization they work for. That’s not Collection Builder’s fault by any means, but it is something to note, especially as we decide when to use what tools and what projects to pursue.
In Paige Morgan’s blog post “How to Get Your Digital Humanities Project Off the Ground,”1 Morgan heavily cautions against making a digital humanities project part of your dissertation. The current status of digital humanities projects in academia is reflected in Morgan’s own experience creating projects while working on a separate dissertation. Morgan notes there were times when the dissertation had to take precedence and the projects suffered. That shouldn’t have to be the case, but from what I have experienced and witnessed, not much has changed between when Morgan wrote the blog post in 2014 and today.
While the cautioning is absolutely valid, and a realistic way of looking at the field and the way academia treats digital humanities projects, I think this advice exacerbates the problem. It’s going to take some people who are willing to push back and say, “No, this is a valid form of scholarship,” to really upend the idea that the only valid way to present mastery over information or share scholarship is the often recursive ouroboros of academic paper and book publishing.
With the rapid pace at which people are expected to graduate, to write, to do, we’ve lost a lot of the time to reflect and a lot of the purpose of academic scholarship. Academia must slow the speed and return to a contemplative pace or start accommodating other modes of scholarship as equally valuable and equally valid (preferably both).
This week I explored the digital art history tool imgs.ai and got some interesting results. imgs.ai provides “a Web-based interface, and machine-learning-based backend that allows the end user to both descriptively and visually search arbitrary image dataset.”1 More simply put, it allows a human to guide an application using computer vision to find images in selected museum databases that are the most similar to an uploaded image, text prompt, or both. The idea being that the user will then continue to engage with more images by selecting from the suggested images that are “positive” or “negative,” furthering the search with this new information.2
The ability to mark negative results is where I hit my first issue: it wasn’t an option for me. This is likely because I was using the site without a login (getting one takes days for approval). While I understand the necessity of gatekeeping databases in the age of AI scraping and how intentionally using AI is fundamentally different from random bots shutting down your site, the irony of the website being protected being built on AI scraping images was palpable. How many of the models imgs.ai uses were built using the same tactics the required login was keeping out? Even if copyright was the driving force instead of defense against bots, how many artworks outside of these museum collections had their copyright violated to train the models to “see”? I am not anti-AI, but I think they are questions worth asking. A team that calls out “Transparency” as one of five “essential criteria”3 should say more about the black box components at work beyond naming the databases or models used.4 Minimally, it should give an explanation of why options are locked behind sign-up instead of forcing the user to guess.
I also wouldn’t be as harsh in my critique if imgs.ai as a tool had provided me an experience that felt more like what the article outlined. To show where imgs.ai gave me interesting results and where it fell short, let me walk you through my experimental searches.
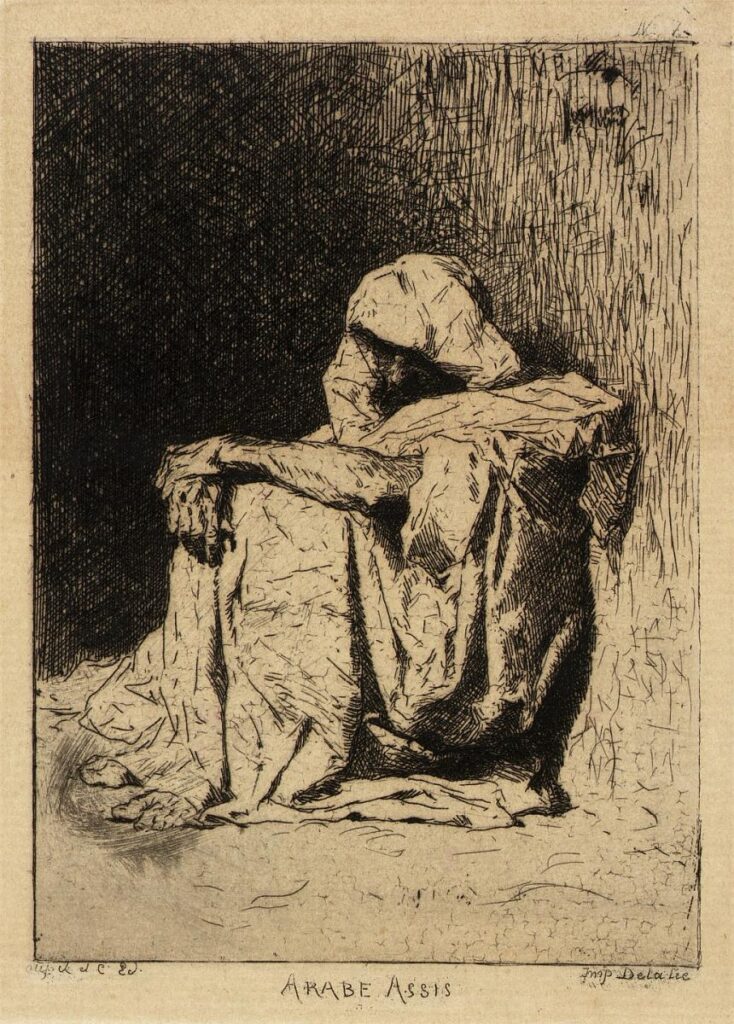
I started with the image from Vermis I: Lost Dungeons and Forbidden Woods I digitized in my last post.5
[Scanned image from Vermis I]. plastiboo, Vermis I: Lost Dungeons and Forbidden Woods, 11th printing, 2026. Used here for educational and commentary purposes; no copyright infringement intended. All rights remain with the original owner.
I knew this wouldn’t necessarily be an easy image with its dithered graphics, but I thought it was fair to work with an image I am actively using in my art history study. While imgs.ai can only show results from the databases it has access to, unlike some other digital art history projects, it does not limit itself to a specific time period or type of art. So I didn’t expect it to return other video game related results necessarily, but I did expect it to be able to get an accurate read on the image’s general contents since testing it with an AI alt text tool had produced flawed but not totally off-base results.
imgs.ai has four feature extractors to choose from for each search, each with a different focus: “stylistic similarity,” pose, “raw color data,” and CLIP which allows combining an image with a text prompt.6
Results were mostly okay if not super useful until I switched to the pose extractor.
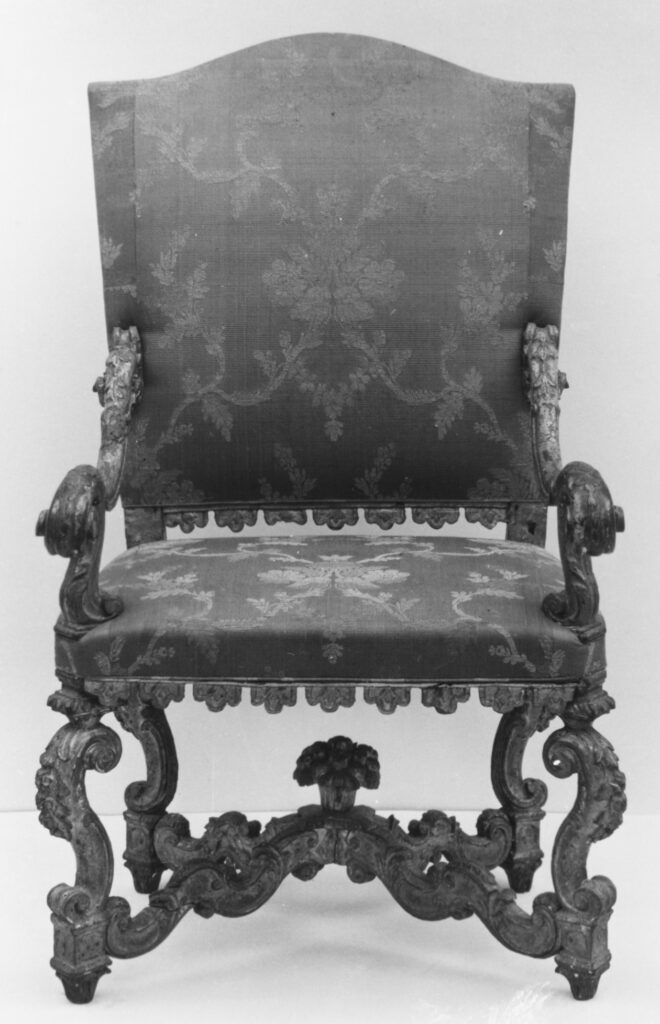
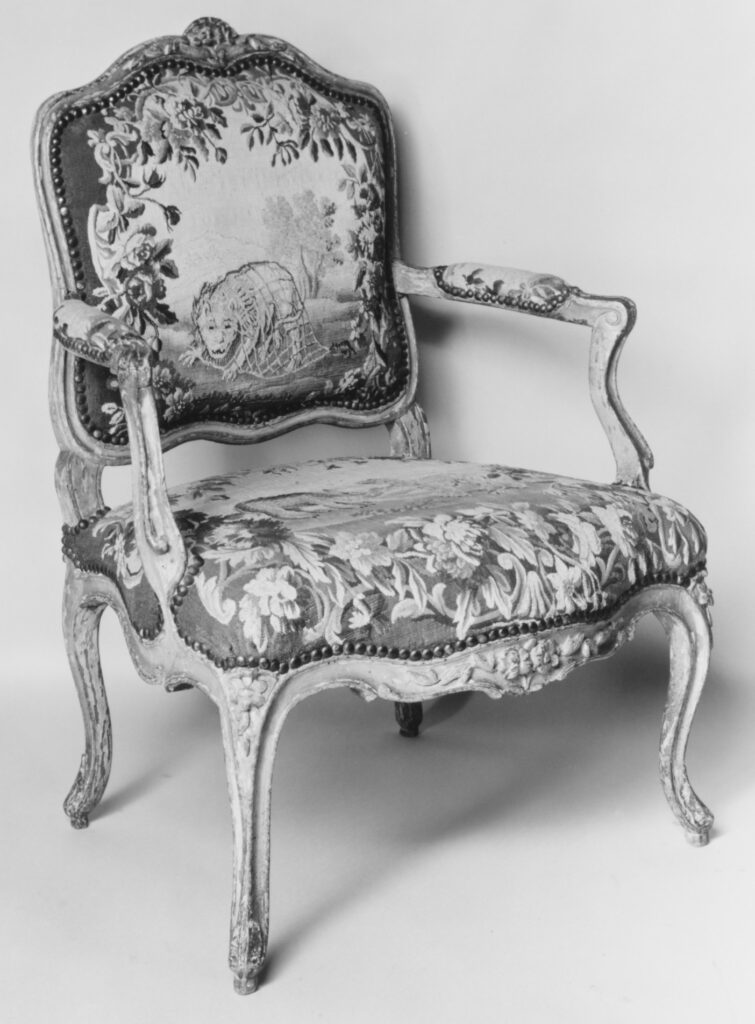
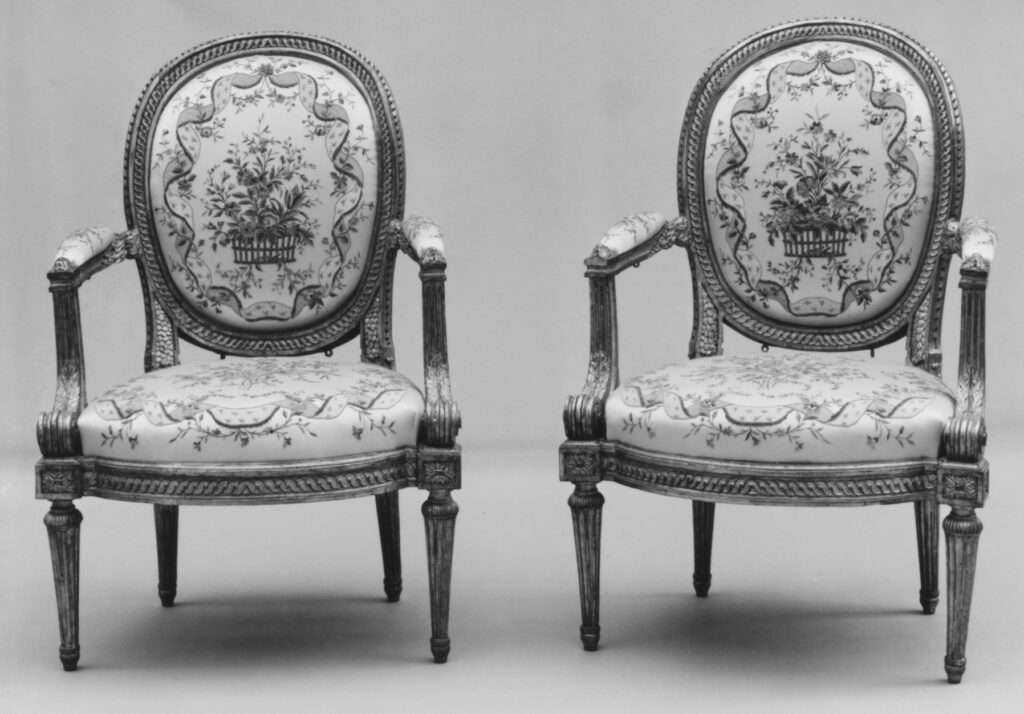
Pair of Armchairs. Late 17th–early 18th century. Carved and gilded walnut, with crimson and gold silk cannelé fabric (not original), Italian. The Metropolitan Museum of Art. Public domain.Manufacture Royale, Aubusson (tapestry weaver). Armchair (part of a set of nine). Mid-18th century. Carved and painted walnut; Aubusson tapestry upholstery, French. The Metropolitan Museum of Art. Public domain.
Well that’s a choice. There weren’t only but a variety of objects that had no relation to the pose regardless of the database used. The chairs would take on an added strangeness with my next search though.
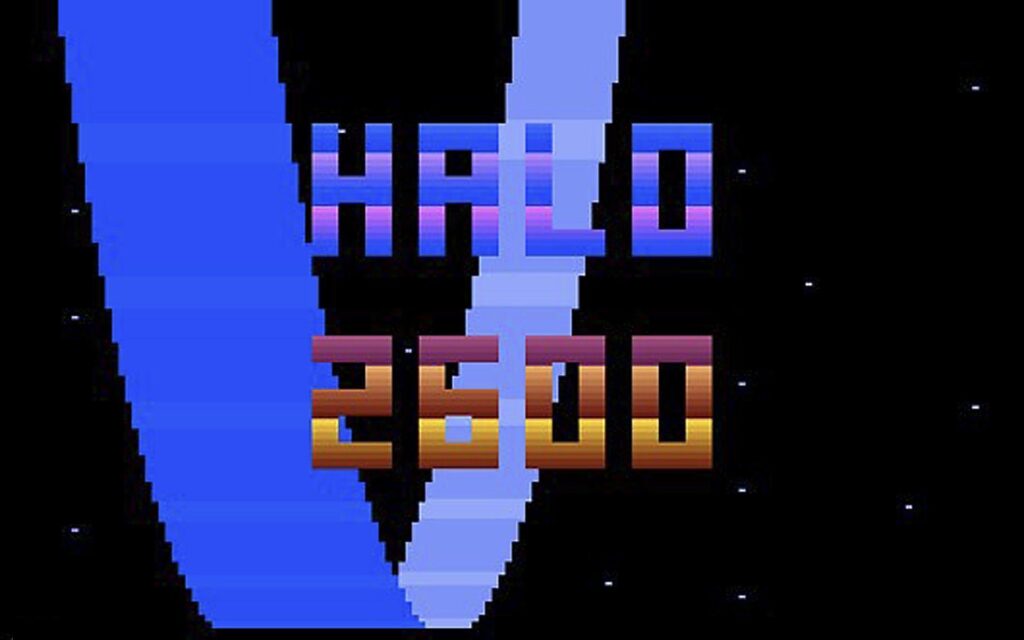
I decided to try another image. One I took directly from the Smithsonian collection.
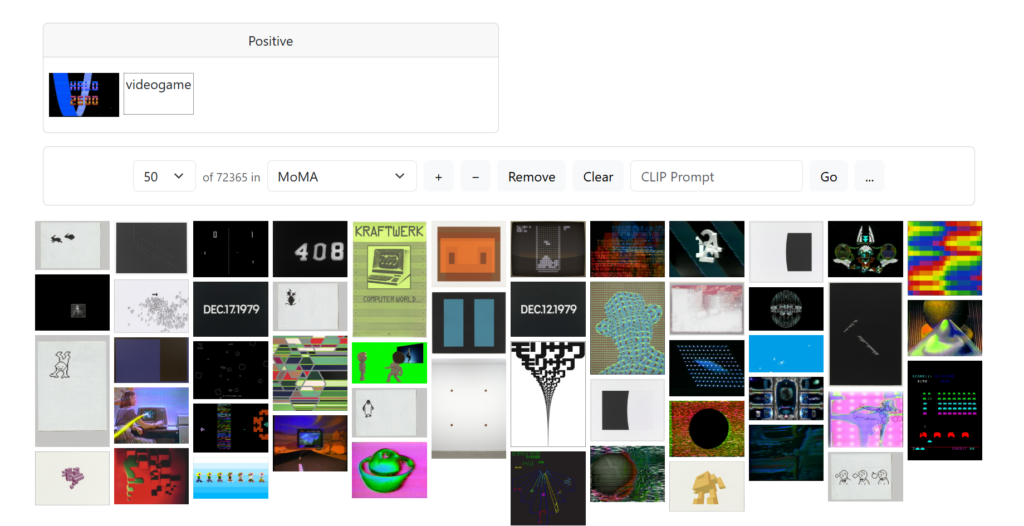
The results were better but still not great. I only got results that were clearly connected to the search image but still novel enough to be useful when I added “videogame” to my CLIP search.
Screenshot of imgs.ai search results for the positive query “videogame” (image: Atari 2600 Video Chess box/screen) within the MoMA collection subset, showing 50 of 72,365 results. Author’s screenshot, 9 Sept. 2026.
All was well until I tried the pose feature extractor again.
Pair of Armchairs. Late 17th–early 18th century. Carved and gilded walnut, with crimson and gold silk cannelé fabric (not original), Italian. The Metropolitan Museum of Art. Public domain.Manufacture Royale, Aubusson (tapestry weaver). Armchair (part of a set of nine). Mid-18th century. Carved and painted walnut; Aubusson tapestry upholstery, French. The Metropolitan Museum of Art. Public domain.
Oh no.
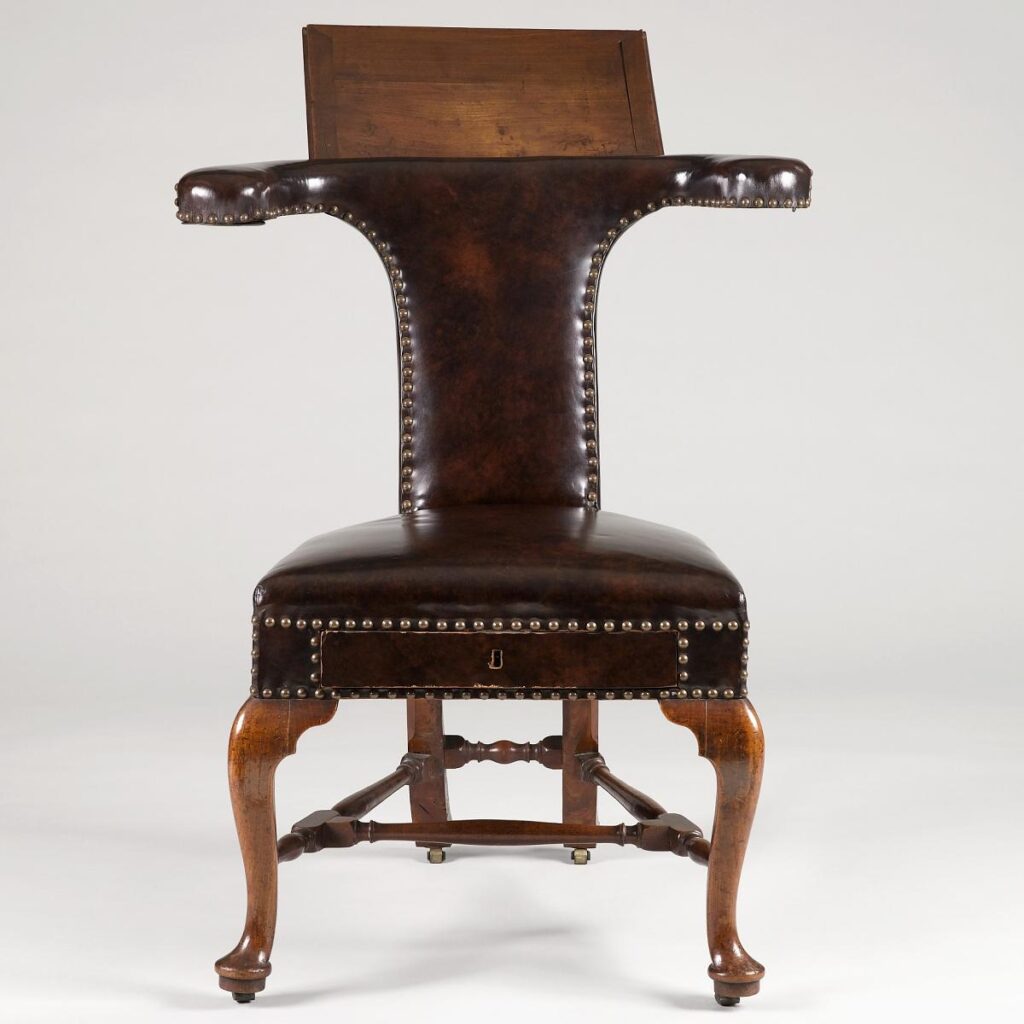
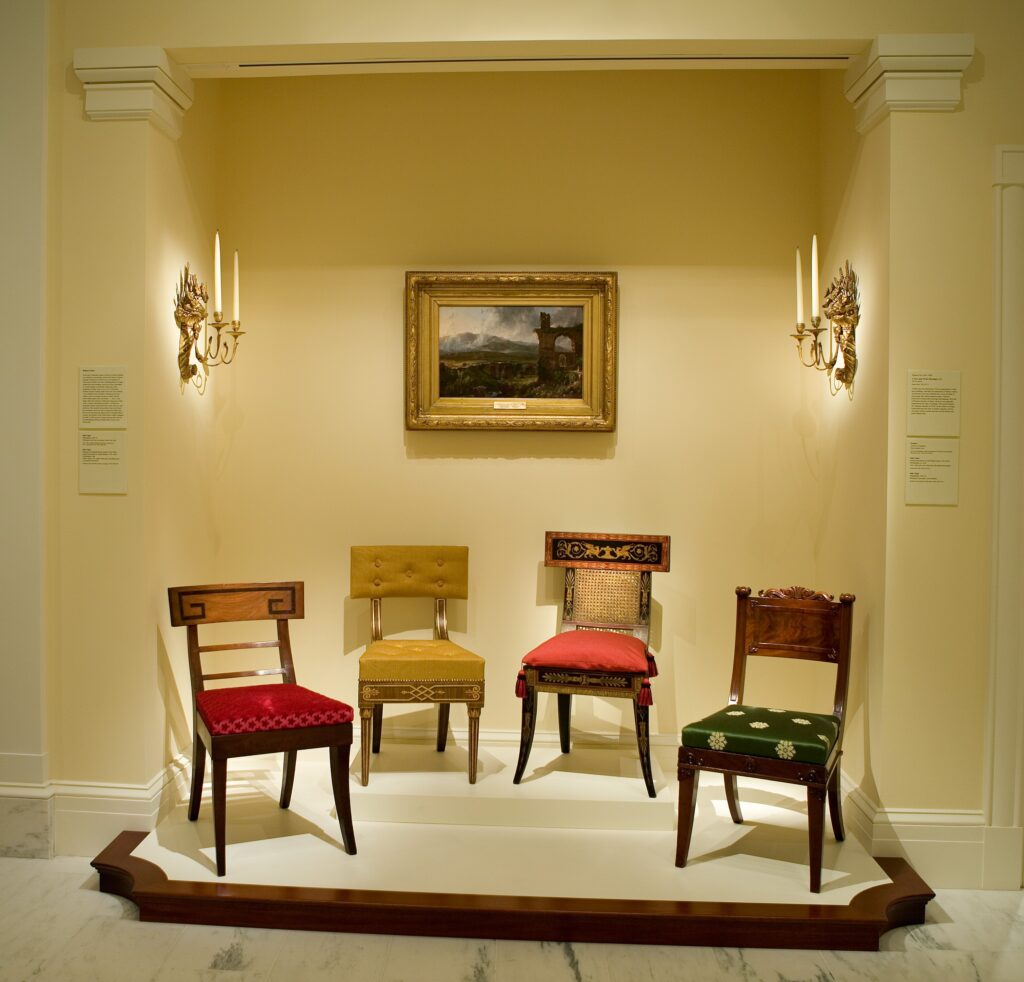
Louis Delanois. Armchair (one of four) (part of a set). ca. 1770. Carved and gilded mahogany, modern silk damask, French, Paris. The Metropolitan Museum of Art. Public domain.Reading Chair. ca. 1720–30. Turned and joined walnut, leather, brass, tin, England. Cooper Hewitt, Smithsonian Design Museum. CC0, public domain.Side Chair. 1815–35. Mahogany, poplar, probably made in Philadelphia, Pennsylvania, American. The Metropolitan Museum of Art. Public domain.
Ohhhh nooooooooo.
I wracked my brain for the cause of this seating-based poltergeist haunting my results. Was it a similarity of a curve in the chair to the curve in the image? Then why were some of the EXACT SAME CHAIRS in the results from both starting images? Other more obvious connection images were not shared between results.
Away from the chairs, most results made sense as to why they were selected. They just didn’t provide anything useful beyond confirmation that yes, it has that color or a frame or someone in armor. Some images I found really intriguing, and they made me think of my image in a different way. It was most successful again when CLIP added texted to the search, in this case, “Skeleton.”
That was when I realized something important. While the point of imgs.ai is not to have an autonomous AI match images, but rather to include the human user in the research loop actively,7 I was doing the heavy lifting for the AI instead of with it. I was taking an image that seemed random to me and taking on the task of finding the connections and assigning meaning. In some ways, this is great. The human should be the one doing those tasks. But I was also struck that I could have done the same cognitive work and gotten the same benefit if the AI had served me completely random images from the collection and told me they were related to my image.
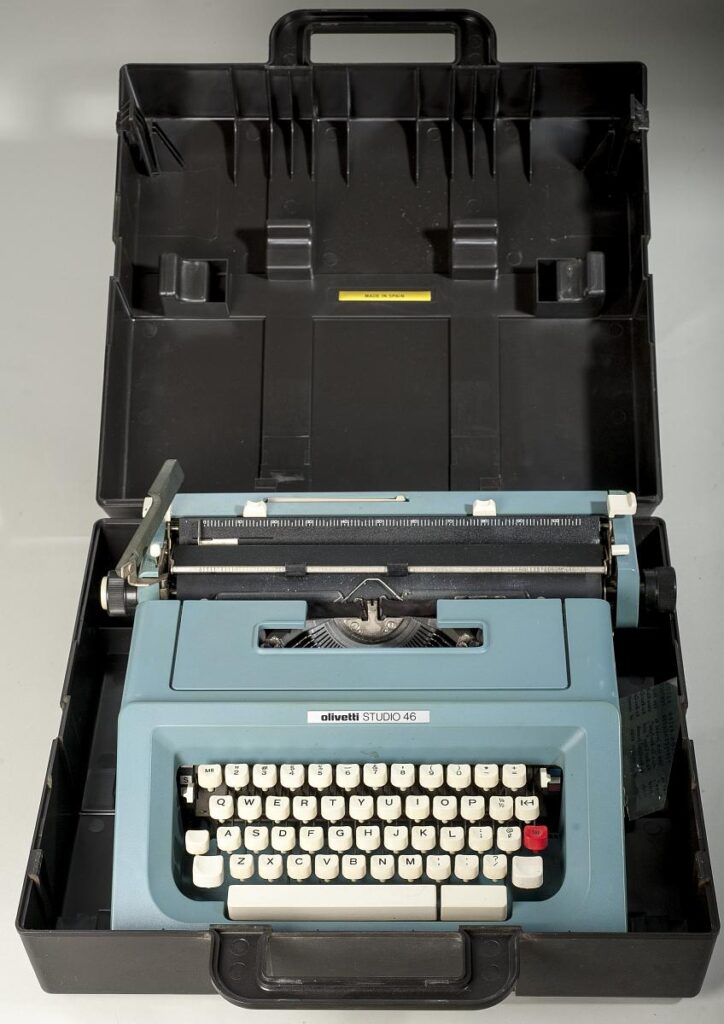
Two more images gave me additional insight into a major issue. Olivia Butler’s typewriter which appeared for both images…
The computer wasn’t “seeing” the artworks as objects but as the images themselves. So not only was the background included but it was given as much consideration as the art. The tool appears to search hierarchically level parts, not the whole.
Perhaps if I had access to the GRAD-CAM to show me where the AI was seeing similarity,8 I would have had a richer experience, but either I could not find that feature or it was behind the login gate. Ultimately, the need driving the creation of the tool seems valid. But until OpenAI understands (not just consumes) Emma Stanford’s “A Field Guide to Digital Surrogates”,10 imgs.ai will be like building a chair with a staple gun: some chance of surprise success, maybe worth the experience, but you can’t make an Eames with it.
Fabian Offert and Peter Bell, “IMGS.AI.: A Multimodal Search Engine for Digital Art History,”International Journal for Digital Art History, no. 9 (2023): 5.30, https://doi.org/10.11588/dahj.2023.9.91295.↩︎
Plastiboo, Vermis I : Lost Dungeons and Forbidden Woods : Official Guide, ed. Michele Nitri, with Marco Cirillo Pedri, Vermis 1 (2023; 11th printing, Hollow Press, 2026), Paperback (Regular Edition).↩︎
Emma Stanford, “A Field Guide to Digital Surrogates,” in The Routledge Companion to Digital Humanities and Art History, 1st ed., ed. Kathryn Brown (Routledge, 2020), https://doi.org/10.4324/9780429505188-19.↩︎
Paul B. Jaskot’s “Digital Art History as the Social History of Art: Towards the Disciplinary Relevance of Digital Methods” questions not only what research questions are best suited for examination using computational tools but what art history itself is. By placing digital art history in the heritage of social art history, Jaskot presents digital art history as capable of changing the art history field like the interventions of feminist and Marxist critiques that came before it. Digital art history is capable of this change by allowing the examination of understudied and noncanonical areas of the field.
The situating of digital art history within social history is not surprising given Jaskot’s background. Jaskot serves as the Co-Director of the Digital Art History & Visual Culture Research Lab at Duke University. His research centers on architecture and Nazi Germany. His projects primarily use GIS to question assumptions about construction and modernism in the era.
One of the more surprising aspects of Jaskot’s article for me was his expansive definition of social art history. Jaskot acknowledges the historical importance of Marxism and feminism and other -isms in reinvigorating art history towards previously unexamined artworks and ideas, but ultimately presents social art history as any approach that treats art and society as deeply interconnected. That relationship is the backbone and focus of social art history. As someone who does not generally consider themselves a social art historian since I rarely use specific identity or political lens, this definition made me reconsider my assessment of my work. My research and projects are often specifically focused on the relational aspect of art and society, mainly understudied areas of video game culture. Even outside that niche, I have an investigative bend in research (likely from growing up watching so much Law & Order as a kid that I played assistant district attorney the way other kids played house). Investigation is about what lives in the cracks of assumptions and following threads of connection to find new truths.
Jaskot also breaks down four of the most common methods used in digital art history: digital storytelling, text analysis, network analysis, and spatial analysis. Jaskot calls out network and spatial analysis as the most used and most fitted to art historical research (as of 2019 when the article was written). This assessment is because Jaskot focuses on large scale projects as the most fertile ground for any type of digital art history. Jaskot is correct that some illuminating projects have used digital art history tools to see areas that would be very difficult to examine without the distance viewing digital art history methods can provide. Network analysis and geographic mapping certainly can work well to preserve large scale complexity alongside a point of view and thesis.
I would be interested to know how Jaskot feels about more recent digital art history projects that use the same tools to look closer than traditional close looking. These projects present a microscopic version of close looking when compared to the space telescope version of distance viewing Jaskot focuses on in the article. One that came to my mind immediately is the presentation of historical research in video games like Pentiment.
Spoiler note: Pentiment – Examples come from interactions that can happen in the first hour or so of the game. I do not touch on the central plot.
Pentiment by Obsidian Entertainment released in 2022, but it’s status in academic research has only continued to grow in the years between then and now (2026). A point-and-click mystery set in Upper Bavaria in the 16th century, Pentiment is extraordinarily well researched. While series like Assassin’s Creed use extensive research in their creation, they often present this research primarily as world building or in objective sounding codex entries that the player can access in the menu. Pentiment embeds the research across the game at all levels. When picking where the player character, a journeyman manuscript illuminator named Andreas, previously studied, you are given the options of Italy, Basel, or Flanders. Each option provides unique dialogue and skills grounded in the history of those places, but also shows how people of different social classes in a small Alpine village conceptualized those places through specific interactions with Andreas.
The art style of Pentiment is also vital to how the game shares insights into perceptions of status, education, and technological progress. Different characters “speak” (via text bubble) in different lettering styles based on Andreas perception of them. The town printer’s speech appears in upside down blocks before reversing into readable script all at once with a clunk. Monks in the scriptorium speak in a flourished ink style that fills in religiously significant words like “Christ” in red after the rest of the text is written. This was a practice I had no idea existed until I search online to see why the script behaved that way.
Pentiment takes this digital narrative presentation beyond research and into a ludic thesis. There are two notable moments early in the game that showed how a ludic thesis could work that stood out to me.
The first moment is when Andreas discovers that a local shepherd is much more well-read then he thought. The shepherd’s speech rewrites itself from a messy illiterate script used for all the peasants to the clear measured text of the academics and educated. The lettering change subtly communicates how status and education worked in the background of all interactions at the time. The second moment is when retrieving books for the Sister who runs the abbey library. As she discusses the books with Andreas, they enter into the books themselves. Here, she has the freedom to explain the lack of choice for women in their lives. She focuses on how this lack of choice is visible in the treatment of the female characters in the books. Women are presented as inherently wicked or only present to suffer for a male character’s benefit regardless of the books being bawdy popular tales, classical texts, or religious allegory.
As the player experiences these moments as Andreas, there is a clear imperative to move beyond enjoyment of the historical setting to reflection on the perspectives about status, equality, progress, and justice that are raised. Despite not explicitly presenting as digital art history, this expansion of purpose makes Pentiment digital social art history. By using digital storytelling, the creators of Pentiment relinquish some control and clarity of their arguments in favor of allowing the player a much closer look than would be possible normally. The player is able to actually control an artist in the time period and choose how to confront the issues raised in game. Despite how the player decides to play Andreas, the reactions of the other characters and the art choices show the clear point of view and arguments being made. It will be interesting to see how new games approach digital storytelling as more works inspired by Pentiment are released. I also wonder if the game studies practice of presenting research in both traditional modes of scholarship and non-tradition modes like game design will expand to other fields).